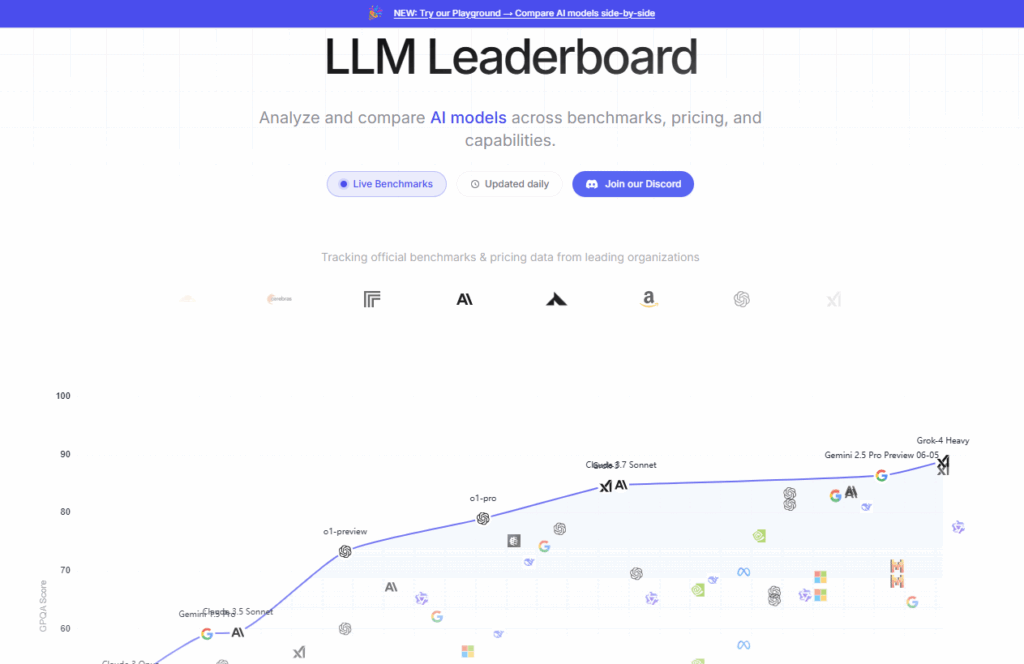
LLM models are highly competitive today. Different models can perform differently across domains and situations, and not every model provides a SaaS or online service you can use directly.
RUNPOD is one cloud-computing option worth considering. You can preload credits and control usage while exploring it. Using my shared link, you can randomly receive a 5-500U credit bonus.
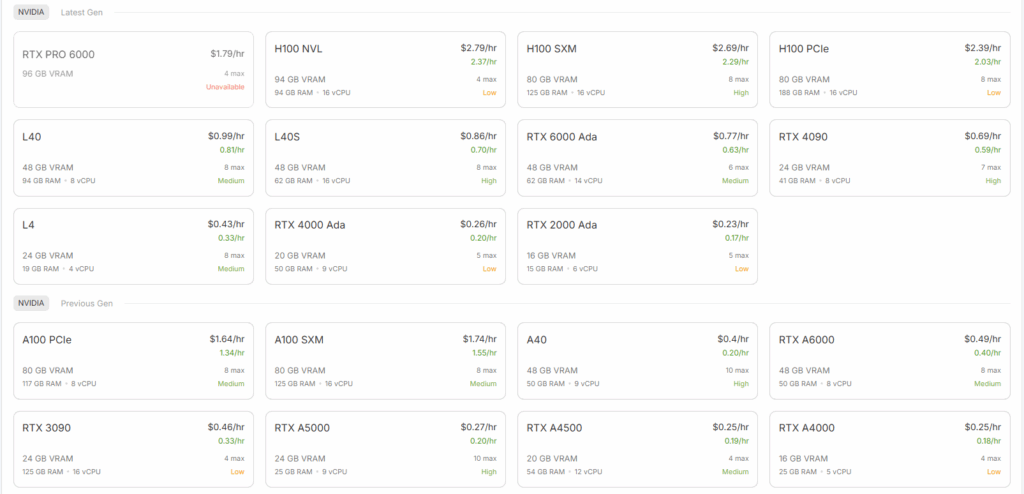
Below are the prices for each machine (2025/07/30).
You can choose the machine specifications you need with the help of AI recommendations.
The most cost-effective RunPod configuration depends on the size and purpose of the AI model you want to experiment with: inference, fine-tuning, or training. Based on the use case here — personal experiments with LLMs or AI models without spending too much — these are the recommendations:
🔥 Best-Value RunPod Configurations (2025 Observation)
| Type | GPU | VRAM | Price (per hour) | Good for |
|---|---|---|---|---|
| 🥇 A100 40GB (Spot) | A100 | 40GB | ~$0.55–$0.70 | Running medium-to-large LLMs, LLaMA2/3, Mixtral, Whisper Large v3 |
| 🥈 RTX 4090 (Spot) | 4090 | 24GB | ~$0.40–$0.55 | Inference, Whisper, Stable Diffusion, fine-tuning smaller models |
| 🥉 RTX 3090 (Spot) | 3090 | 24GB | ~$0.25–$0.35 | Running small-to-medium models, Whisper, small fine-tuning jobs |
| 🚀 Low-Cost Testing | T4 / 2080Ti | ~16GB | ~$0.10–$0.20 | Trying models, simple inference, or quantized-model tests |
✅ Prefer Spot instances when possible to reduce cost. RunPod provides interruption-tolerant mechanisms, making them suitable for workloads that are not long-running training jobs.
👨🔬 AI Model Experiment Recommendations for Beginners and Individual Users
✅ Inference & Testing (No Fine-Tuning)
- Recommended models:
- LLaMA 3 8B (Q4_K_M or GPTQ)
- Mistral 7B (Q4)
- Phi-2
- Whisper small/medium/large
- Stable Diffusion 1.5 / SDXL (for image generation)
- Recommended hardware:
- RTX 3090 or 4090
- 24GB VRAM is enough for most INT4 models
- Lower cost, suitable for longer experiments
- RTX 3090 or 4090
✅ Fine-Tuning or LoRA (Small Models)
- Recommended models:
- TinyLlama / Phi / Mistral 7B / LLaMA 7B
- Use PEFT + LoRA
- Recommended hardware:
- A100 40GB
- Supports full FP16 fine-tuning or larger LoRA training
- More expensive per hour, but faster completion can reduce total cost
- A100 40GB
💡 Ways to Reduce Cost
- Use Spot instances: 40~70% cheaper, and RunPod can automatically restore files.
- Use quantized models (Q4_K_M, GGUF, GPTQ): reduce VRAM usage and run 7B models on 16~24GB GPUs.
- Configure auto-shutdown: automatically stop the machine after use to avoid wasting money.
- Use Hugging Face + exllama / llamacpp: reduce inference resource use, especially on GPUs with less VRAM.
📦 Simple Selection Guide
| Goal | Recommended GPU | Model size |
|---|---|---|
| Whisper, SD, small-LLM inference | RTX 3090/4090 | ≤7B |
| Medium LLM fine-tuning or inference | A100 40GB | ≤13B |
| Fast Tiny LLM testing | T4 / 2080Ti | ≤3B quantized |
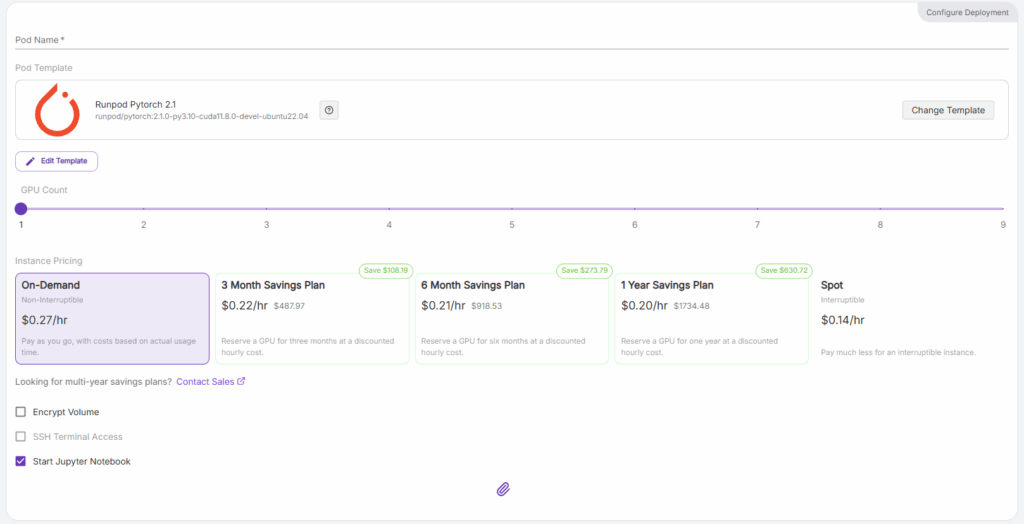
Once you choose the specification you want, you can start the machine. If you only want to test things, you can use On-Demand. From past experience, though, a machine may be reclaimed after a few minutes or a few hours, so it is not always the most economical option. Also pay attention to Volume usage. If you want model data to remain temporarily available after shutdown or reclamation, configure storage first.
That is a simple introduction to RUNPOD. If you are interested, give it a try ☺
You can also use my referral link for a random $5-500 credit bonus.