Topic Hub
Local AI, Models & Compute
Model capability is only half the story. The other half is hardware, VRAM, inference frameworks, deployment, and the surrounding environment. This hub collects my practical work running models locally and on on-demand compute.
What will you find here?
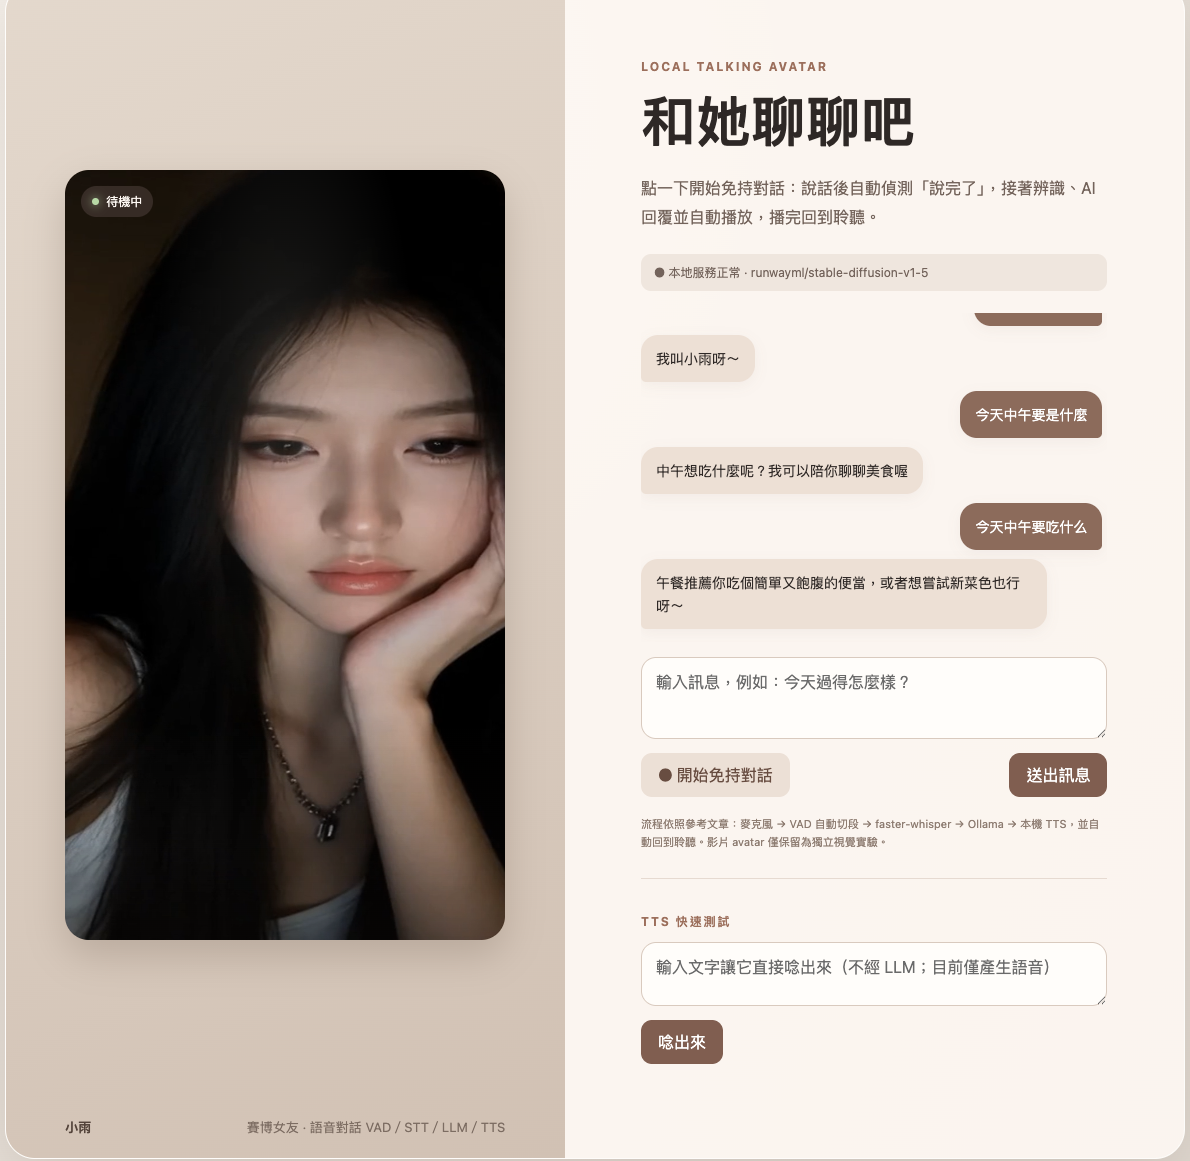
- • How local AI and realtime voice agents are assembled
- • How GPU and VRAM constraints shape model workloads
- • When local hardware, cloud GPUs, or mobile environments make sense
- • Practical tradeoffs in model deployment and development environments